Data matching in logistics refers to associating operational information from different sources with each other in an accurate, consistent and usable way. Many data fields such as order data, stock information, product description, shipment record, vehicle plan, delivery status and customer information are parts of the same flow in the logistics process. However, if this information does not support each other correctly, serious problems may occur in the process. This is exactly why data matching is important. The aim is not only to collect data, but to ensure that the data progresses in harmony with each other.
Many operational errors in logistics begin in the information flow before the physical flow. The product description on the system may not match the reality of the warehouse, the address information in the order may not be reflected correctly in the shipment plan, the product that appears to be in stock may not be available on site, or customer notification may be delayed because the delivery record is processed in a different format. Although the problem that appears in such problems seems operational, its source is often data incompatibility. Data matching is the core work to reduce this incompatibility.
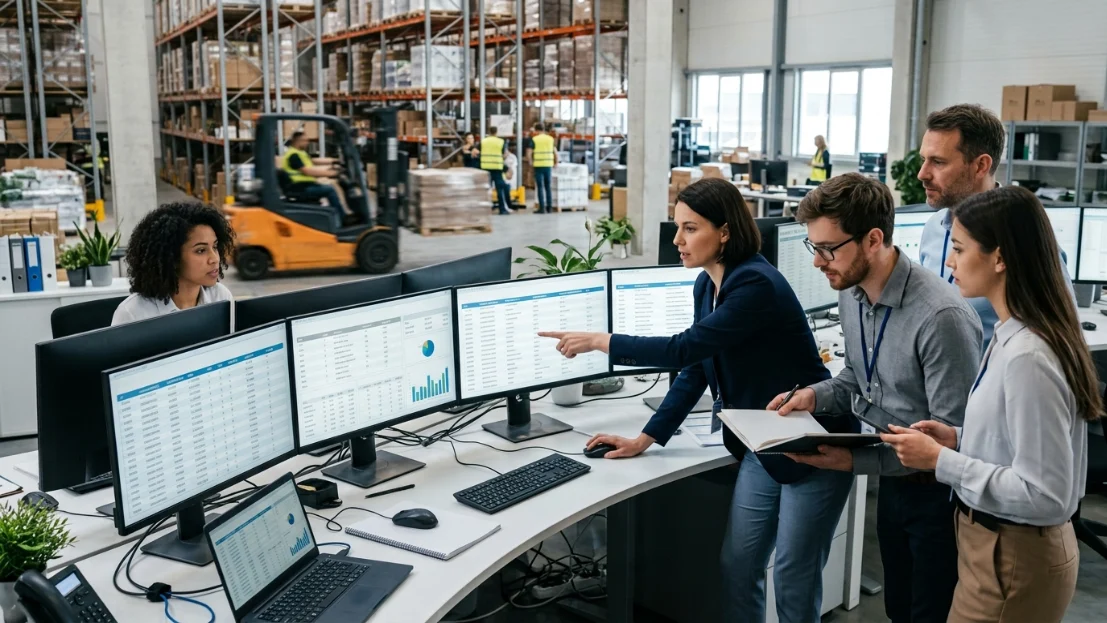
This concept becomes especially critical in structures where different departments work on the same operation. The sales order opens, the warehouse prepares the product, the operation plans the shipment, and the field team completes the delivery. If these teams are moving forward with different versions of the same information, there will be a disconnect in the process. Data matching reduces this disconnection and creates common data ground. Thus, the process is not only faster, but also more accurate.
Today, logistics softwareplays an important role in establishing and managing data matching processes. However, the main issue here is not to use technology, but to correctly define how and in which areas the data will be combined. Because no matter how much data there is, information that does not support each other can complicate the operation rather than improve it. Therefore, data matching in logistics should be seen as one of the basic building blocks of digitalization.
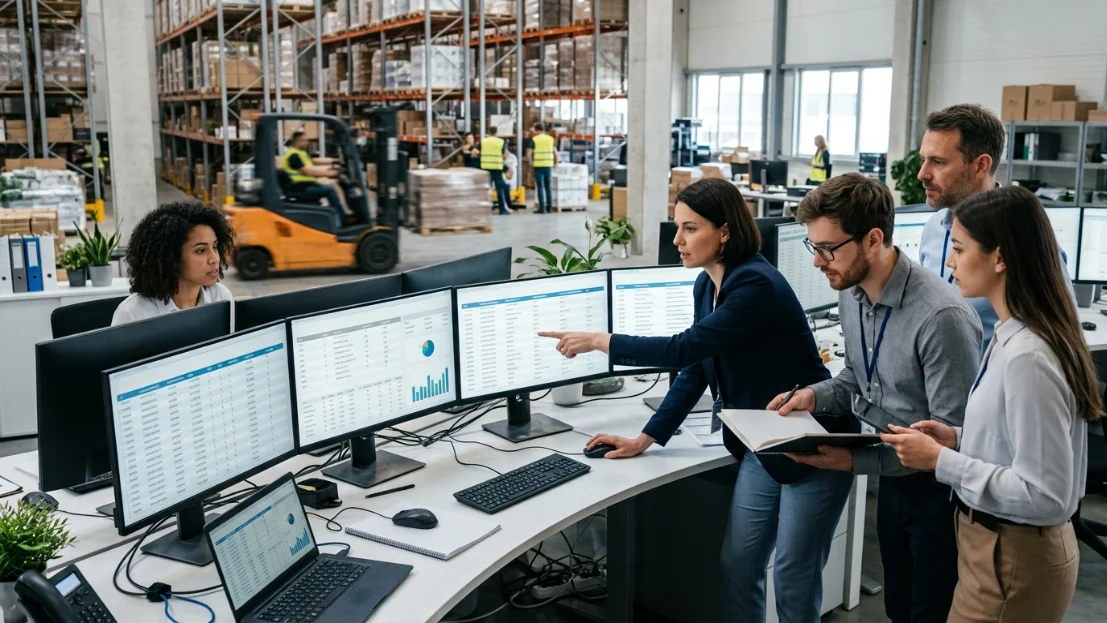
The Place of Data Matching Concept in Logistics Operations
The place of the data matching concept in logistics operations is to ensure harmony between physical flow and digital record. In logistics, where the product actually is is as important as where it appears in the system. Information such as the stage at which the order is progressing, how the shipment is planned, whether the delivery has been completed or not is not enough if it is individually accurate; They must also be compatible with each other. Data matching ensures this integrity.
This concept often works invisible within the operation, but its impact is huge. The practical equivalents of data matching are the progression of a product code between the order record and the warehouse label with the same logic, the error-free transfer of customer information to the delivery plan, or the correct reflection of the shipment status in reporting. If this structure is weak, there is a need for constant control, correction and manual intervention in the process. This both wastes time and increases the risk of error.
Data matching is also essential for decision accuracy. Management evaluates the operation according to the data it sees in the system. If this data is inconsistent across different areas, the decisions made will be poor. Vehicle planning may be based on incorrect order density, stock decisions may be based on faulty visibility, or delivery performance may be read with incomplete data. Therefore, data matching is the basis not only of record order but also of decision quality.
Another important aspect of this concept is that it reduces repetitive operating errors. The fact that the same information appears differently in different places creates a need for constant control in the process. When data matching is strong, the process becomes more spontaneous. Because teams can focus on managing the operation rather than constantly validating data. This creates a significant advantage in terms of efficiency.
Key Information Fields Involved in Data Matching in Logistics
The first key information field involved in data matching in logistics is order data. When the order number, product code, quantity information, delivery address, priority level and customer notes are processed correctly, the entire subsequent flow proceeds more smoothly. Even a small mismatch in order data can directly impact warehouse readiness, shipping schedule and delivery success. Therefore, the first round of data matching often starts on the order side.
The second important area is stock and product information. The product description appearing on the system and the physical counterpart in the warehouse must be compatible. Product code, batch information, quantity, location and availability should follow the same logic in different areas. If product information does not match the order, incorrect picking, missing output, or delay may occur. Therefore, data matching is especially critical for warehouse accuracy.
Shipment and vehicle plan information are also among the basic fields. Information such as which order is connected to which shipment, which vehicle will go on which line, route order and distribution region must match the order and delivery data correctly. If this connection is weak, the shipping plan is set up incorrectly, the delivery order is disrupted and field performance decreases. Therefore, data matching is necessary not only for the product and order, but also for the action plan.
Another area is delivery and closing information. Information such as whether the product was delivered, at what time it was delivered, whether the delivery failed, whether there is a need for return or rescheduling, must be accurately linked to the order and shipment records. Otherwise, customer information, performance reports and service quality measurement will remain weak. Therefore, data matching remains important in the final stage of the operation.
The Impact of Data Matching on Process Accuracy and Operational Compliance
The first effect of data matching on process accuracy is that it reduces the possibility of incorrect operations. When order, stock, shipment and delivery information is compatible with each other, teams experience less hesitation on the same operation. It becomes clear which shelf the product is on, which order it belongs to, which shipment it will be shipped with and what the delivery result is. This clarity both reduces the error rate and makes the workflow more reliable.
From an operational alignment perspective, data matching enables different teams to act on common data. When sales proceed with different information, warehouse with different records, and shipment with different lists, harmony in the process is disrupted. When data matching is strong, all actors of the same operation rely on the same foundation. This increases not only internal coordination but also the speed of intervention. Because action can be taken directly instead of first discussing which information is correct.
Another impact is on the quality of visibility. Management reports, operating charts, and performance measurements are only as good as the accuracy of the data. Mismatched data produces misleading visibility. Matching data, on the other hand, more accurately shows which area is working really well, where there are problems, and which process needs improvement. Therefore, data matching affects management quality as well as process accuracy.
Finally, data matching increases operational compliance and reduces the need for unnecessary manual checks. When teams don't have to constantly compare information, correct records, and resolve conflict, they can focus more of their energy on planning, executing, and improving. This provides both speed and quality advantages in the process. Data matching is therefore an invisible but highly effective area of operations.
Points to Consider in Data Matching Structure in Logistics
The first thing to consider in data matching structure in logistics is the data standard. Having the same product with different codes, identifying the same customer differently in different areas, or not keeping delivery information in a common format weakens the matching process. Therefore, it should first be clarified which data will be defined by which rule. Non-standard data makes the matching structure fragile from the start.
The second important point is the reliability of the data source. Information may come from different places, but if it is not clear which source is the main reference, there will be confusion in the process. The data source considered essential for order data, stock status, shipment plan and delivery result should be clearly defined. Otherwise, different departments will accept different records as correct and the incompatibility will grow.
Another point of attention is that data matching should not be seen only as technical integration. Of course, inter-system connectivity is important, but the real issue is business logic. It should be clear which field will match which field and why, which data will be considered critical for which decision, and which deviation should generate an alarm. Otherwise, technical connection is established, but real harmony cannot be achieved in the process.
Finally, the data mapping structure should be checked regularly. As the operation grows, new products are added, new customer types arrive or different locations come into play, the data structure becomes more complex. The matching model, which seems sufficient at first, may become inadequate over time. Therefore, data mapping should not be considered as a one-time installation, but as a structure that is regularly reviewed and improved. Only in this way can sustainable accuracy be achieved.